MotherDuck CEO Says Single-Node Analytics Can Outperform Distributed Systems
Jordan Tigani, MotherDuck CEO, argues that many analytics teams are paying a complexity tax for workloads that never needed it.
While continuing to learn more about MongoDB, specifically the synergy with WiredTiger, I’ve come to notice there is more than one way client writes can be throttled.
If you haven’t followed my journey while battling with MongoDB, check out my previous post, MongoDB: One write, two logs, where a client write gets persisted and replicated inside a classical replica set. Supporting files for this article are on GitHub.
The first and best-known one is flow control, the write back pressure most of us have already met. A write counts as majority-committed once most of the replica set members acknowledge it. In a three-node replica set, that means the primary plus at least one secondary. If no secondary acknowledges, the majority commit point stops moving.
MongoDB tries to keep that commit point within ten seconds of the primary (with default configuration). It starts throttling at half of that, around five seconds behind. Nothing is rejected, writes just slow down. The primary hands out fewer write tickets until the commit point moves again, but never fewer than a hundred tickets per second.
We won’t talk about flow control here, because in production the throttling came from the primary itself. How is that possible? Let me explain.
You’ve read my previous post :), so let’s start assuming some basic understanding of MongoDB -> WiredTiger communication. Every DML statement modifies a page in the WT cache.
If we trace a write to a collection, the page holding that document becomes dirty inside the cache (if it is in the cache in the first place, otherwise it first gets read in from the data files). The page no longer matches what is on disk, and that mismatch is WT’s signal that the page has to be reconciled before the memory can be reused. Dirty pages leave the cache by one of two routes. Eviction runs continuously in the background. Checkpoints run every 60s by default.
The write itself does not wait for either of them. WT appends every modification to the write-ahead journal while the affected page stays dirty in cache, and that append is what makes the write survive a crash (classical write ahead log mechanism). MongoDB flushes the journal every 100ms by default, storage.journal.commitIntervalMs, and immediately for a write that asks for j:true, so the exposure is that interval rather than the 60 seconds between checkpoints. If mongod dies between checkpoints, recovery replays the journal and rebuilds the pages from it. This is also what lets the primary acknowledge a write before its page is rewritten, which is how dirty content piles up between checkpoints. None of it touches collection-*.wt or index-*.wt on disk.
Eventually the pages have to move, and that is the checkpoint’s job. It reconciles the pages that are still dirty and writes them to the data files as a snapshot consistent up to a single timestamp (MVCC), the same one across every collection and index. Pages that eviction already cleaned are skipped. The previous checkpoint stays valid while the new one is written, and the new one becomes permanent when WT updates its metadata table in one atomic step to point at it. Only then can the journal records it covers be discarded, which is what bounds journal growth.
The cache has a fixed size, so something has to keep it from filling up. One eviction server walks the cache and picks candidates. Worker threads, by default four, do the heavy lifting.
When the threads start, their progress is governed by four thresholds. They are two pairs measuring fullness and dirty percentage of the cache.
The first pair watches how full the cache is. If we cross 80 percent, eviction_target, the workers start freeing space in the background. If we cross 95 percent, eviction_trigger, the application threads are summoned to help the workers.
The second pair watches how much of that cache is dirty, using the same scale, with much lower numbers. Cross 5 percent, eviction_dirty_target, the workers start to evict dirty pages. If we cross 20 percent, eviction_dirty_trigger, the application threads join in.
In a write-heavy workload the dirty pair is the one you meet first. A cache that is 30 percent full can be 30 percent dirty if every page in it was written, which is past the 20 percent trigger and nowhere near the 80 percent line.
The logic is simple. The target starts the workers, and the trigger is the point where workers have “lost the battle” and need help from application threads. This is also the point where client writes start getting throttled.
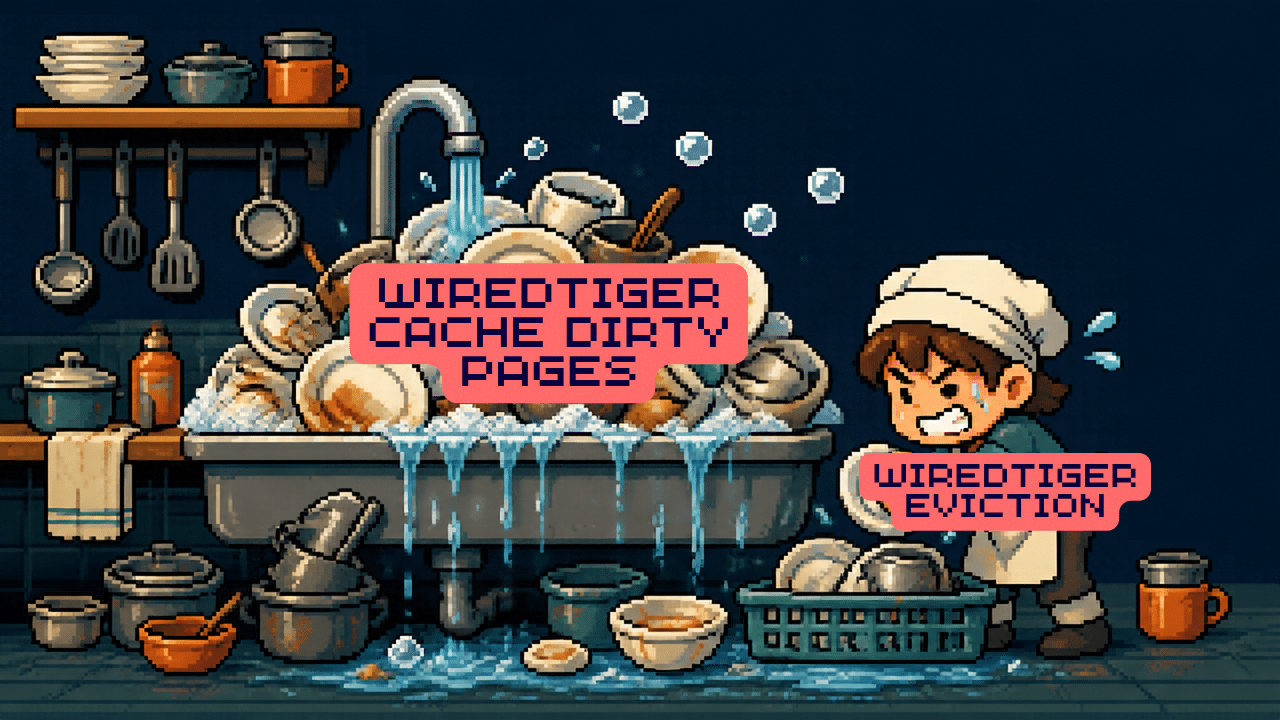
An excellent analogy to the upper mechanism is a restaurant. Waiters are application threads. They take orders and carry plates, which is your reads and writes. The kitchen shelf is the cache and holds a fixed number of plates. A clean plate is a page that matches the data files and can be reused. A dirty plate is a page somebody changed.
The dishwashers are the eviction workers. While they keep up, nobody in the dining room notices. If we pass a point where there are too many dirty plates, the dishwashers cannot keep up, so we pull in the waiters. Since the waiters are now washing dishes, taking orders slows down, new dirty plates arrive more slowly, and the kitchen gets its chance to catch up. And never mind the review the customer leaves after waiting too long :D.
Two details keep the analogy honest. A plate somebody is still eating from cannot be collected. That is a page pinned by an active reader, and it is a real reason eviction stalls while the cache keeps growing. And the trigger is not a request. An application thread that finds the cache past a trigger does the eviction itself, before it can read or write any more data. That is the latency you feel.
In my scenario this meant I needed more dishwashers, more time for them to work, or both.
The workload was bulk writes that also triggered extra reads. That needed fixing at the source, but first I needed to reduce the backpressure. This cluster ran MongoDB 8.3.8. The version matters because the available configuration parameters differ between releases. The first change was to increase the eviction thread count from 4 to 20. On 8.3.8, dedicated server parameters allow this at startup or runtime:
db.adminCommand({
  setParameter: 1,
  wiredTigerEvictionThreadsMax: 20,
  wiredTigerEvictionThreadsMin: 20
})
More threads alone were not enough. I also wanted dirty-page eviction to start earlier, giving the workers more time before application threads had to join in. That meant lowering eviction_dirty_target from 5 percent to 1 percent.
There is a dedicated wiredTigerEvictionDirtyTargetGB parameter, but it only takes effect at startup and accepts an absolute size. For a 15.5 GiB cache, 0.155 would approximate a 1 percent target. Changing the percentage on the running instance required the raw WiredTiger configuration. The dirty-target part of that change was:
db.adminCommand({
  setParameter: 1,
  wiredTigerEngineRuntimeConfig: "eviction_dirty_target=1"
})
MongoDB’s manual advises against changing this parameter without direction from MongoDB engineers because it has implications across both WiredTiger and MongoDB.
Neither runtime command persists across restarts. The thread parameters can be stored under setParameter in mongod.conf.
The result was 20 eviction threads available instead of 4, with background dirty-page eviction starting at 1 percent instead of 5 percent of the cache. That target is about 159 MiB on a 15.5 GiB cache. It is not a cap: dirty content can rise above it, and the dirty trigger remains at 20 percent.
There is a cost to starting earlier and allowing more workers to participate. Eviction can consume more CPU and disk I/O. Setting both thread limits to 20 also prevents the thread count from scaling down, although those threads can wait when there is no work. For this workload, the aim was to absorb more of the eviction work in the background before it reached the application threads.
Even a two-parameter change can change how the cluster behaves, from incidents and slowdowns during write inflow to steady work across all workloads.
The important thing is to understand the underlying technology and the mechanisms underneath. Understanding the why’s and the how’s. AI is incredible at helping us gain more knowledge and understanding, but we are the ones making the decision.
This is the next step in software engineering I’m comfortable with.