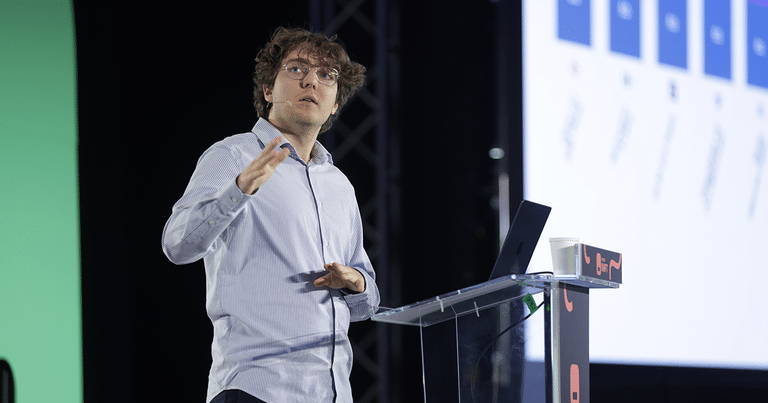
NVIDIA’s Igor Dmochowski explained that LLMs are no longer limited just by model size or benchmark scores; the cost of longer reasoning means runtime, context length, memory use, and throughput matter just as much.
The AI boom is no longer just a race to build faster machines. The real challenge now is making all the moving parts work together at scale.
> subscribe shift-mag --latest
Sarcastic headline, but funny enough for engineers to sign up
Get curated content twice a month
Written by people, not robots - at least not yet. May or may not contain traces of sarcasm, but never spam. We value your privacy and if you subscribe, we will use your e-mail address just to send you our marketing newsletter. Check all the details in ShiftMag’s Privacy Notice